A look at automatic image description using vision-language models: what works, what breaks, and what it means for web accessibility.
Titilayo OshinowoFranklin W. Olin College of EngineeringApril-May 2026
01 - Project Motivation & Introduction
Making the web more accessible with computer vision
A vast majority of images that can be found on the web contain no alt-text: the short written descriptions that screen readers use to convey image content to visually impaired users. The goal of this project is to explore whether a modern vision-language model can generate useful alt-text automatically, and where it falls short.
What is alt-text and why does it matter?
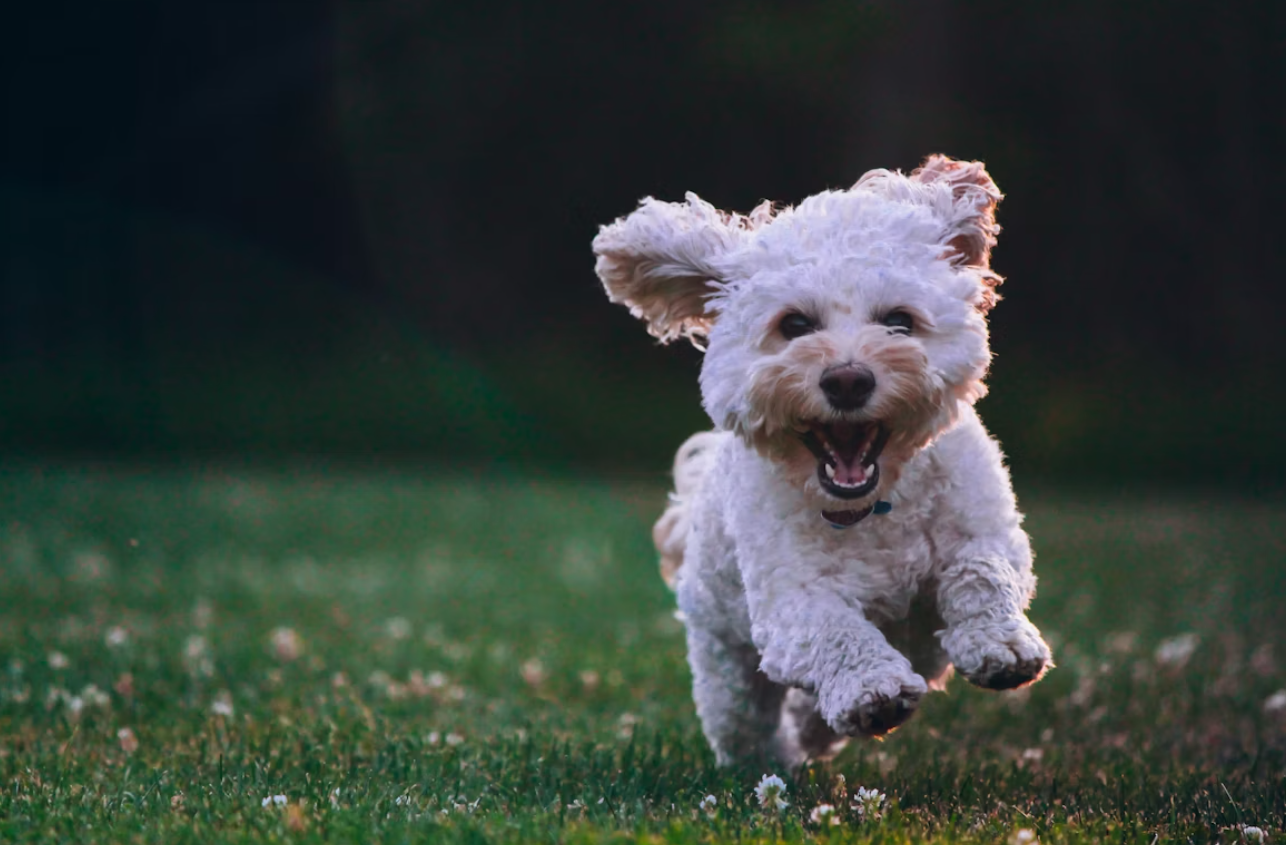
Alt-text is an HTML attribute that allows screen readers describe images to users who can't see them. Below is an example of this tag
A small white dog is running through the grass
Without it, images are completely silent: users hear nothing, or just a raw filename.
According to WebAIM's annual accessibility survey, missing or inadequate alt-text is one of the most common accessibility failures on the web. The scale of the problem is enormous and mostly unaddressed.
WCAG 2.1 requires that all non-decorative images have a text alternative that serves the same purpose as the image. That standard is widely unmet.
What does good alt-text look like?
WCAG 2.1 (the Web Content Accessibility Guidelines) defines several principles for good alt-text:
It should describe the content and function of the image, not just what's visible
Decorative images should have empty alt attributes (`alt=""`)
Text in images must be included in the description
Context matters: the same image might need different alt-text in different settings
Based from our list above the last point is where automated tools struggle most.
Project Structure
This project asks: can a modern vision-language model generate alt-text that's actually useful? And where does it fail, and for whom? Based on these goals this site will walk through the full project in four sections
How the Model Works: a plain-language explanation of BLIP
Implementation:the code setup of the model and explanation
Processing: how the model processes the image outputs
Evaluation: where the model succeeds and fails
Try it yourself: view the video summary, try out the code, and write your own code
02 - How the Model Works
From image to language
For this project we will be using BLIP (known as Bootstrapping Language-Image Pre-training),
it is a vision-language model that translates images into natural language descriptions.
Unlike traditional computer vision systems that classify objects,
BLIP generates full sentences. This makes it well suited for alt-text,
which requires not just recognition, but explanation.
Model Architecture
BLIP uses two core components which are:
Vision encoder (known as ViT): Where the image is split into patches and encoded into feature vectors.
This allows for the model to understand objects, layout, and visual structure.
Language decoder: This is a transformer that generates text token-by-token,
conditioned on the image features.
These components are trained together on large image-text datasets,
allowing the model to learn how visual patterns correspond to language.
What the Model Actually Does
Conceptually, the model performs this pipeline:
Image → Feature Extraction → Language Generation → Caption
Why this Matters for Alt-text
Alt-text is not just labeling images, it needs the images to contain a descriptive meaning.
Unlike classifiers that output single words, BLIP generates full sentences,
making it better suited for accessibility tasks.
Note: Even though, this model is good at captioning it does not mean that it is good completely at accessibility field.
The goal of this project is to explore that gap.
03 - Implementation
What was actually built
This project was implemented in Google Colab using the PyTorch library and a dataset from Hugging Face.
The project pipeline includes dataset loading, preprocessing, model fine-tuning, and inference.
To access this project click here: Colab Notebook
---
Environment setup
For this project, the model was trained on an NVIDIA A100 GPU (provided on Google Colab Pro) to handle large batch sizes
and accelerate training. Essentially, it is used to enhance speed.
CUDA available: True
GPU: NVIDIA A100-SXM4-80GB
---
Dataset: real alt-text, not captions
The dataset that is used for project is Flickr30k with original alt-text, not generic captions.
Each image contains multiple human-written descriptions.
raw = load_dataset("Mozilla/flickr30k-transformed-captions")
Train: 4500 images
Eval: 500 images
Expanded to 22,500 training examples due to multiple captions per image
Each image contributes several training samples, significantly increasing dataset size.
---
Custom dataset construction
A custom PyTorch Dataset from Hugging Face was built to expand each image into multiple
(image, caption) pairs.
for item in hf_dataset:
  for cap in item["original_alt_text"]:
    self.samples.append({"image": image, "caption": cap})
This is important: that the model learns from multiple descriptions of the same image,
which improves robustness but also introduces variation.
---
Preprocessing
The images and text are then processed together using the BLIP processor.
Padding tokens are masked out during training to prevent them from affecting loss.
---
Training configuration
The model was then fine-tuned using Hugging Face's Seq2SeqTrainer.
Using 3 epochs
Learning rate of: 3e-5
A Batch size: 16 (with gradient accumulation)
The Effective batch size: at 128
Use of a Cosine learning rate scheduler
Containing early stopping enabled
gradient_accumulation_steps = 8
fp16 = True
---
Training results
Epoch
Train Loss
Validation Loss
1
16.72
2.08
2
14.16
2.01
3
12.57
2.02
As we can see, the training loss appears to decrease steadily, while the validation loss stabilizes,
thus indicating that the model learns general patterns but plateaus quickly.
---
Inference Pipeline
A reusable function was created to generate captions from:
From local images
From uploaded images
From image URLs
out = model.generate(
  **inputs,
  max_new_tokens=50,
  num_beams=4
)
The usage of beam search improves caption quality by exploring multiple possible outputs.
---
Example output
True: Two boys playing near a lake throwing rocks
Predicted: Two children are playing near a body of water
The model captures the scene correctly but simplifies important details.
---
What this shows
This pipeline demonstrates that performance depends on more than the model:
dataset structure, preprocessing, and training strategy all shape the output.
04 - Processing
How Preprocessing Affects Output
Before reaching our model, the images are transformed into a fixed format.
These preprocessing choices directly impact caption quality.
Small visual changes can lead to large language differences.
Key finding
The model is highly sensitive to detail and context.
When information is lost, captions become vague.
Image Processing Experiments
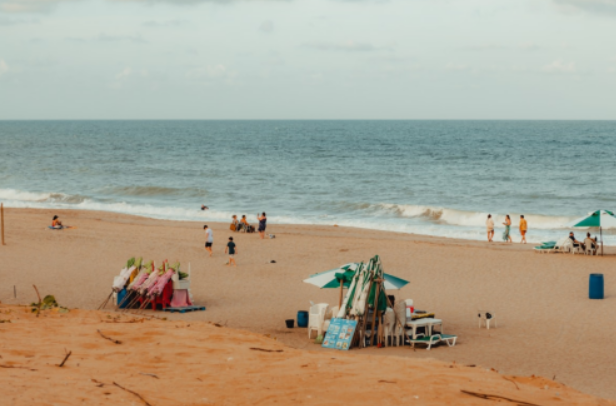
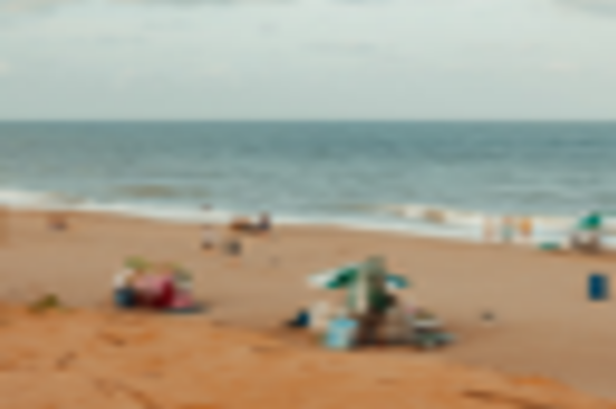
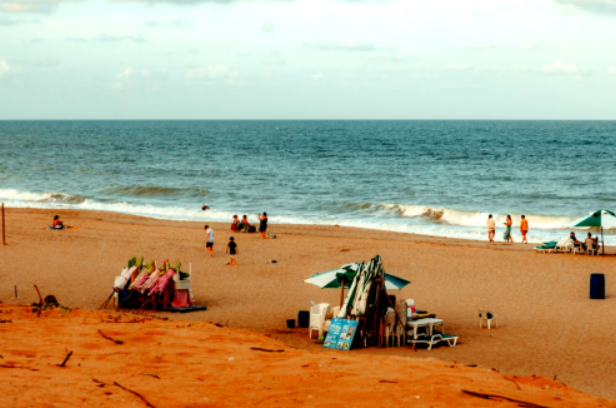
The model's output depends heavily on how images are prepared.
Resolution
Original
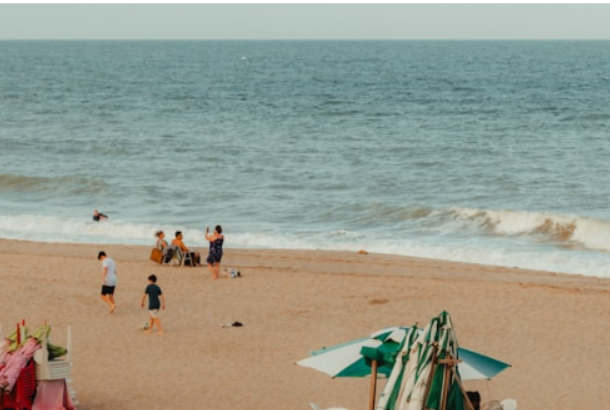
"A beach with a lot of people on it"
Alright
Low Resolution
"A group of people are sitting on the beach under umbrellas."
Partially Right
Lower detail reduces caption specificity.
Cropping
Contrast
"A beach with a lot of people on it"
Mediocre
Cropped
"A group of people are walking on the beach"
Alright
Removing context leads to vague outputs.
05 - Evaluation
What Works and What Breaks
Where the Model Succeeds
The model can recognize common objects and scenes
It can produces fluent, grammatical descriptions
Captures overall structure of an image
Where it Fails
It misses specific actions (for example, “throwing rocks”)
Potentially removes important contextual details
The model struggles with text inside images
Ignores accessibility intent
A caption can be correct but still not useful for accessibility.
This reveals a key limitation: the model is optimized for describing images,
not for communicating meaning to a user with specific needs.
Understand and Explore the System
Instead of just interacting with the final model, this section lets you
understand how the system works and experiment with it directly.
Project Walkthrough
In this short video, I walk through the deliverables of this project: motivation, model, implementation,
and key findings of the project.
Project Explanation Video
Covers model design, training process, and key limitations.
Run the Full Project
This notebook contains the full implementation: dataset loading,
preprocessing, training, experiments, and evaluation.